Enterprise AI Operations

What Is LLMOps? Managing Large Language Models in Production

Deploying a large language model is only the beginning. LLMOps is the discipline that keeps AI systems reliable, safe, and measurable once they're live — and it's becoming the deciding factor for enterprise AI success.

Talk to Our AI Team
Enterprise AI infrastructure for managing large language models in production

LLMOps, Defined

LLMOps — Large Language Model Operations — is the set of engineering practices, tooling, and governance processes that organisations use to deploy, monitor, update, and scale LLMs in live production environments. Think of it as MLOps, purpose-built for the unique demands of foundation models: prompt management, output evaluation, cost control, safety guardrails, and continuous fine-tuning.

Why LLMs Break Down After Launch

Getting a prototype working is the easy part. Keeping it accurate, safe, and cost-efficient under real user load is where most enterprise AI initiatives stall.

📉

Model Drift

LLM outputs degrade over time as real-world language, context, and user expectations shift — often invisibly, with no automatic alert.

💸

Runaway Inference Costs

Unmanaged token usage scales linearly with traffic. Without cost controls, a single high-volume endpoint can consume entire AI budgets in days.

🔒

Safety and Compliance Gaps

Unguarded models hallucinate, leak sensitive data, or produce outputs that violate regulatory requirements — creating serious legal and reputational exposure.

🔀

Prompt Fragility

Prompts that work perfectly in staging fail unpredictably in production when inputs vary — and there's no version control to trace the change.

🧩

Integration Complexity

LLMs rarely stand alone. Connecting retrieval pipelines, APIs, databases, and orchestration layers creates brittleness that's hard to debug at scale.

📋

No Evaluation Framework

Without structured quality benchmarks, teams can't measure whether a model update improved or degraded real-world performance before shipping it.

AI engineer monitoring LLM performance in production

How LLMOps Differs From Traditional MLOps

MLOps was built for predictive models with numeric inputs and discrete outputs. LLMs operate in a fundamentally different regime — open-ended text, massive parameter counts, and emergent behaviour that resists traditional metrics.

  • Prompt versioning instead of feature pipelines
  • Token-based cost optimisation, not compute-hour budgets
  • Semantic evaluation rather than accuracy/F1 scores
  • RAG and retrieval pipelines as first-class infrastructure
  • Output safety and guardrail layers with no MLOps equivalent
  • Fine-tuning and RLHF feedback loops at scale

The Seven Pillars of a Mature LLMOps Stack

A production-grade LLMOps practice spans these seven capability areas — each one a prerequisite for running enterprise AI at confidence.

Prompt Management & Versioning

Store, version-control, and A/B test every prompt template. Treat prompts as code: branches, diffs, rollback, and staged releases included.

Observability & Monitoring

Track latency, token consumption, error rates, and output quality in real time — with alerting that fires before users notice degradation.

Evaluation & Quality Gates

Benchmark outputs against ground-truth datasets using semantic similarity, human preference, and domain-specific rubrics before every release.

RAG Pipeline Management

Maintain retrieval-augmented generation pipelines — keeping vector indexes fresh, retrieval relevance tuned, and document ingestion automated.

Cost & Token Optimisation

Route queries to the right model tier by complexity, cache frequent responses, and set per-endpoint budget limits to contain inference spend.

Safety & Guardrails

Apply content filtering, PII detection, output validation, and role-based constraints to prevent harmful or non-compliant responses at the API layer.

Fine-Tuning & Feedback Loops

Collect user feedback, flag low-quality outputs, and feed structured signal back into fine-tuning or RLHF cycles to continuously improve model performance.

Building LLMOps in Four Phases

Most enterprises move through four stages — from initial deployment to full operational maturity.

1

Foundation — Deploy & Instrument

Stand up your first production endpoint, connect logging and tracing, and establish baseline latency and cost metrics. The goal is visibility before optimisation.

2

Control — Prompt Ops & Guardrails

Introduce prompt versioning, a staging environment for prompt changes, and safety layers — content filters, PII detection, and output validation — before expanding user access.

3

Optimise — Cost, Quality & RAG

Implement model routing, response caching, and token budgets. Build and maintain RAG pipelines where retrieval is needed. Add an evaluation harness with automated quality gates for every release.

4

Scale — Feedback Loops & Governance

Operationalise fine-tuning pipelines, integrate user feedback signals, and implement cross-team governance — usage policies, model cards, audit trails — to support enterprise-wide AI deployment.

Key Tools Enterprise Teams Rely On

No single platform handles every layer of LLMOps — most enterprise stacks combine purpose-built tools across the lifecycle.

Orchestration: LangChain, LlamaIndex, Haystack
Observability: LangSmith, Helicone, Arize AI
Evaluation: Ragas, DeepEval, TruLens
Prompt Mgmt: PromptLayer, Promptfoo, Agenta
Vector Stores: Pinecone, Weaviate, pgvector
Guardrails: NeMo Guardrails, Guardrails AI
Fine-Tuning: Vertex AI, Azure ML, OpenPipe
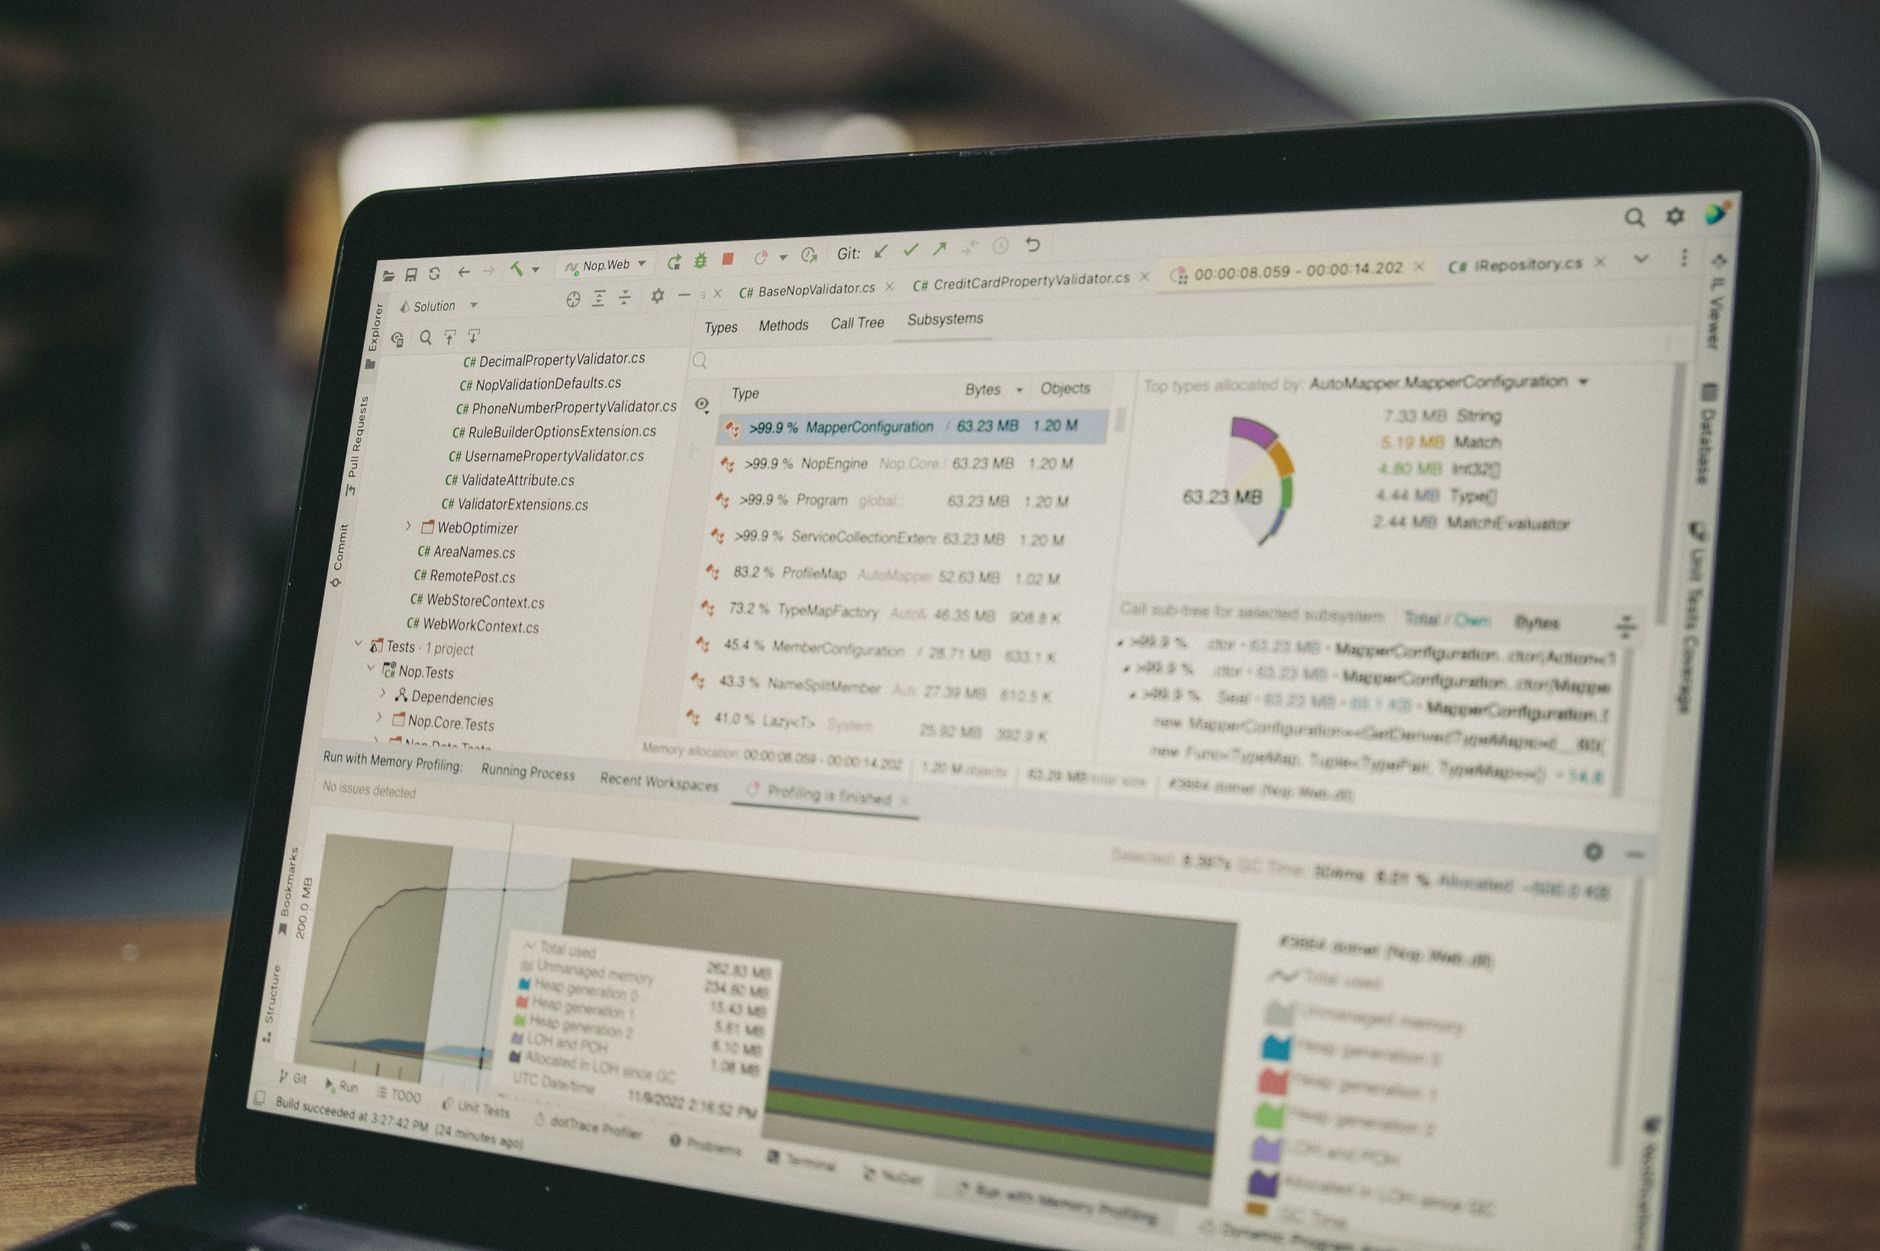
LLMOps toolchain dashboard for monitoring and evaluation

Signs Your Organisation Is Ready to Invest in LLMOps

LLMOps isn't just for AI-native startups. These signals indicate an enterprise is at the inflection point where operational discipline pays off.

  • ✓ You have at least one LLM-powered feature or workflow in production
  • ✓ Prompt changes go directly to production without testing
  • ✓ You have no visibility into token costs per endpoint or user session
  • ✓ Model output quality is assessed manually — or not at all
  • ✓ Multiple teams are building with LLMs but using different tools and standards
  • ✓ Your legal or compliance team is asking questions you can't yet answer about AI outputs
  • ✓ You're planning to scale to more users, use cases, or markets in the next 12 months

LLMOps FAQ

What's the difference between LLMOps and MLOps?
MLOps manages the lifecycle of traditional machine learning models — feature engineering, training pipelines, and numeric predictions. LLMOps addresses the unique challenges of large language models: prompt versioning, open-ended output evaluation, retrieval-augmented generation, and token-based cost management — none of which have direct MLOps equivalents.
Do I need LLMOps if I'm just using an API like OpenAI?
Yes. Even if you're not training your own model, you still need to manage prompt versioning, monitor output quality, control costs, and enforce safety policies — all of which are LLMOps concerns. The risks of not doing so grow significantly as user volume and use-case criticality increase.
How long does it take to build an LLMOps practice?
Basic observability and prompt management can be in place within four to six weeks. A full production-grade stack — including evaluation harnesses, RAG pipeline management, and fine-tuning loops — typically takes three to six months to mature, depending on team size, existing tooling, and the number of active AI workloads.
How much does LLMOps infrastructure cost?
Costs vary widely. Open-source tooling can cover most observability and evaluation needs at low direct cost, but requires engineering time to operate. Managed platforms range from a few hundred to several thousand dollars per month depending on scale. The business case is usually framed against inference cost reduction and avoided production incidents — organisations typically see LLMOps pay for itself within the first quarter of deployment.
Is LLMOps the same as AI governance?
They overlap but aren't identical. AI governance covers policy, ethics, accountability, and regulatory compliance at an organisational level. LLMOps is the operational layer that makes governance enforceable in practice — guardrails, audit logs, output filtering, and access controls that turn governance policy into production behaviour.
Which enterprises need LLMOps most urgently?
Any enterprise with LLMs in customer-facing workflows, regulated industries (finance, healthcare, legal), or multiple internal teams independently building AI products should treat LLMOps as a priority. The risk of inconsistent quality, runaway cost, or a compliance breach scales with adoption — and LLMOps is how you stay ahead of it.

Ready to Operationalise Your AI?

Turn Your LLM Deployment Into a Reliable, Scalable System

Our AI engineering team helps enterprise organisations build LLMOps practices from the ground up — from initial observability to full fine-tuning pipelines. Book a free 30-minute discovery call and leave with a concrete next step.

Book Your Free Discovery Call

No commitment required — just a practical conversation about your AI stack.

Leave A Comment

Categories

Archives

Tag